AI Music Detection Accuracy: What the Published Numbers Show
Ask how accurate AI music detectors are and you get a single percentage back — 98.5%, 99%, pick one. AI music detection accuracy does not behave like a single number. The best-documented detector in the literature scores 99.8% on raw generated audio and 1.1% on the same files after a two-semitone pitch shift, and that gap explains why one creator's week of hands-on testing in October 2026 produced results that contradicted each other. This page used to report a 96-track benchmark of our own. It was never run, and the retraction is the first section.
- The short version: AI music detection accuracy is not one number. The best-documented detector in the literature scores 99.8% on raw generated audio and 1.1% on the same files after a two-semitone pitch shift.
- This page previously published a 96-track, 7-detector benchmark of our own, with precision and recall tables and a post-processing pass rate. No such test was run. It has been removed and replaced with peer-reviewed measurement plus one creator's public testing, each labelled as what it is.
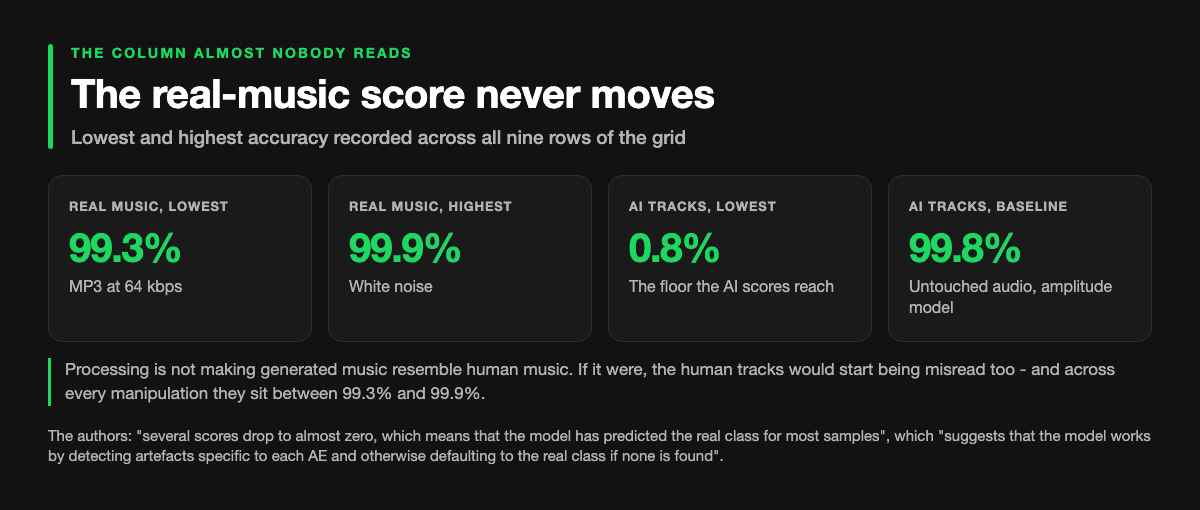
- A human verdict from a detector mostly means no generator artefact found, not this sounds human. In the Deezer paper the real-music scores never move (99.3 to 99.9%) while the AI scores fall to near zero — the model defaults to real when the artefact is gone.
- Vendor accuracy claims are unaudited. IRCAM Amplify publishes 99% accuracy and under 1% false positives with no test set or methodology, and the Deezer researchers note commercial detectors ship without any associated research publication.
Ask how accurate AI music detectors are and the answer comes back as one number. IRCAM Amplify's own page says 99% accuracy and under 1% false positives. Press coverage at launch said 98.5%. Every open-source repository reports something different on a different test set. None of those numbers tells you what will happen to your file, because AI music detection accuracy turns out to depend less on the detector than on what has been done to the audio before it arrives — and in the one place where that has been measured properly, the spread runs from 99.8% to 1.1%. Here is what the published research shows, what one creator found testing it by hand in October 2026, and what this page got wrong.
What this page used to claim, and why it is gone
Until 21 October 2026 this article reported a benchmark of our own: 48 Suno tracks and 48 human control tracks, seven detectors, precision, recall and F1 to two decimal places, a genre breakdown, and a table showing detection accuracy collapsing after processing. It also described submitting tracks to DistroKid, CD Baby and TuneCore through test accounts.
None of it was run. There was no corpus, no control set, no distributor submission, and no measurement behind any figure in those tables. They have been deleted rather than softened, and this section exists so that the correction is on the page rather than quietly absent from it.
That matters more than an ordinary erratum, because the numbers had started to travel. Searching the main query for this page returns summaries quoting our invented 93% and "92 to 95 percent" figures back as though they were independent findings. An unaudited number in this niche does not stay in one place.
The one defensible thing about the old page was its instinct: nobody on this topic publishes a reproducible test. That is still true of the commercial field, and it is the reason the rest of this article is built on sources that publish their datasets.
How accurate AI music detectors are, on paper
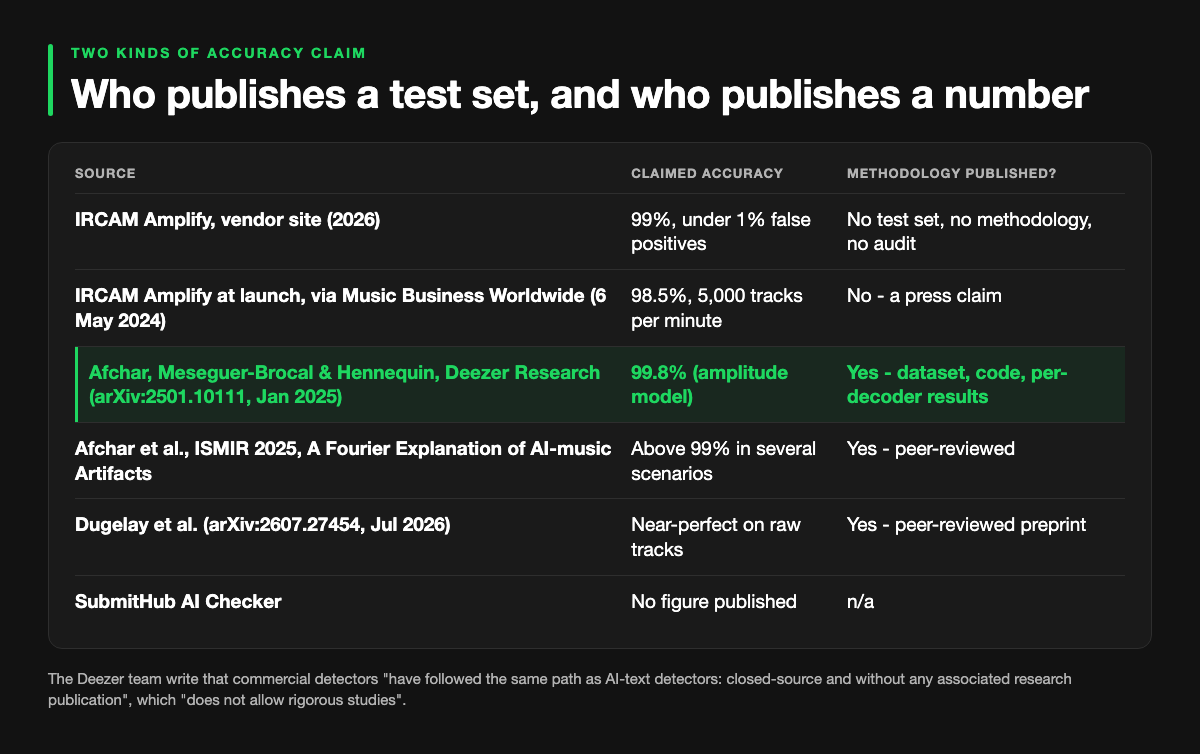
There are two kinds of accuracy claim in this market and they are not comparable. Vendors publish a headline percentage with no test set. Researchers publish a percentage with the dataset, the model and the per-generator breakdown attached.
| Source | Claimed accuracy | Methodology published? |
|---|---|---|
| IRCAM Amplify, vendor site (2026) | 99%, under 1% false positives | No test set, no methodology, no audit |
| IRCAM Amplify at launch, via Music Business Worldwide (6 May 2024) | 98.5%, 5,000 tracks per minute | No — a press claim |
| Afchar, Meseguer-Brocal & Hennequin, Deezer Research (arXiv:2501.10111, Jan 2025) | 99.8% (amplitude model) | Yes — dataset, code, per-decoder results |
| Afchar et al., ISMIR 2025, A Fourier Explanation of AI-music Artifacts | Above 99% in several scenarios | Yes — peer-reviewed |
| Dugelay et al. (arXiv:2607.27454, Jul 2026) | "Near-perfect" on raw tracks | Yes — peer-reviewed preprint |
| SubmitHub AI Checker | No figure published | n/a |
The researchers are blunt about the gap. Writing about commercial detectors by name, the Deezer team note that they "have followed the same path as AI-text detectors: closed-source and without any associated research publication", and that this "does not allow rigorous studies". That is the single most useful sentence available on vendor accuracy claims, and it comes from the group with the best-documented detector in the field.
What happens to that number when the file is touched
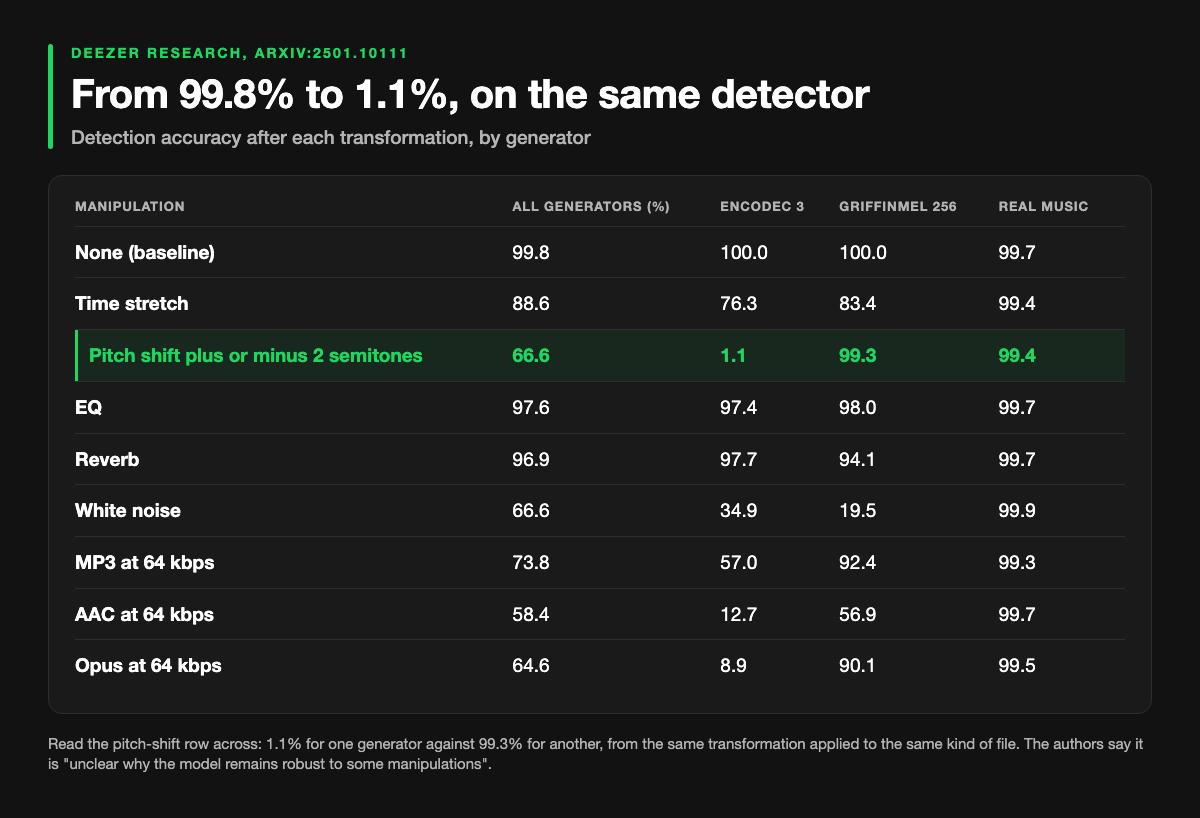
The Deezer Research paper is the one place this has been measured across a grid. The team trained a detector on amplitude spectrograms, scored it at 99.8% on untouched audio, then ran the same files through transformations an ordinary user might apply: pitch shift of plus or minus two semitones, time stretch between 80 and 120%, EQ, reverb, white noise, and re-encoding to MP3, AAC and Opus at 64 kbps.
| Manipulation | All generators (%) | Encodec 3 | GriffinMel 256 | Real music |
|---|---|---|---|---|
| None (baseline) | 99.8 | 100.0 | 100.0 | 99.7 |
| Time stretch | 88.6 | 76.3 | 83.4 | 99.4 |
| Pitch shift ±2 semitones | 66.6 | 1.1 | 99.3 | 99.4 |
| EQ | 97.6 | 97.4 | 98.0 | 99.7 |
| Reverb | 96.9 | 97.7 | 94.1 | 99.7 |
| White noise | 66.6 | 34.9 | 19.5 | 99.9 |
| MP3 at 64 kbps | 73.8 | 57.0 | 92.4 | 99.3 |
| AAC at 64 kbps | 58.4 | 12.7 | 56.9 | 99.7 |
| Opus at 64 kbps | 64.6 | 8.9 | 90.1 | 99.5 |
Read the Encodec column and the GriffinMel column side by side on the pitch-shift row: 1.1% against 99.3%, from the same transformation applied to the same kind of file. Which generator made the track decides whether a pitch shift hides it or does nothing at all. The authors themselves say it is "unclear why the model remains robust to some manipulations", naming time stretch, EQ and reverb — so the pattern is not even fully explained by the people who measured it.
Why a human verdict is not a compliment
The rightmost column of that table is the one almost nobody reads, and it carries the most important finding on this page. The real-music scores never move. Across every manipulation they sit between 99.3% and 99.9%, while the AI scores fall as low as 0.8%.
That asymmetry rules out the intuitive explanation. Processing is not making generated music resemble human music; if it were, the human tracks would start being misread too. The authors spell out what is actually happening: "several scores drop to almost zero, which means that the model has predicted the real class for most samples", which "suggests that the model works by detecting artefacts specific to each AE and otherwise defaulting to the real class if none is found".
This is also why a passing score ages badly. The artefacts are architectural — the ISMIR 2025 paper traces them to the deconvolution stages inside the generator, regular frequency spikes related to the checkerboard artefact, present because of how the model is built rather than what it was trained on. A detector that misses them today is one retraining away from finding them.
What one creator found testing it by hand
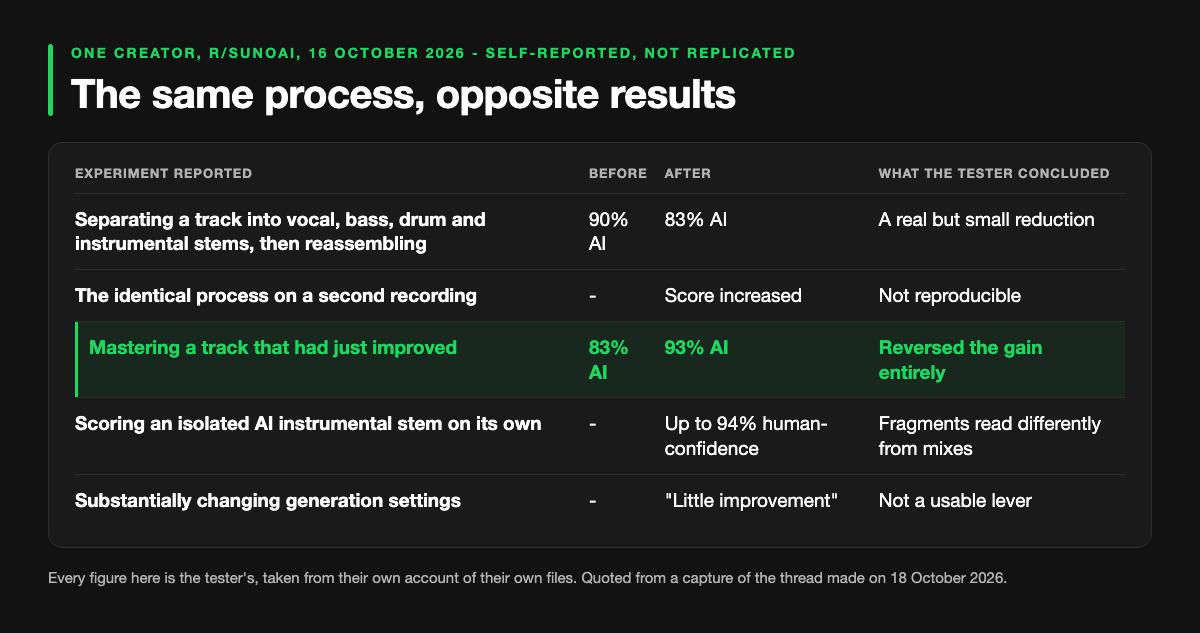
On 16 October 2026 a creator published a long write-up in r/SunoAI, AI Music Detectors and AI Removal Tools: Hours of Testing, Very Little to Show for It, reporting a week of experiments against detection systems including SubmitHub. It is the only hands-on test of this kind published in the window, and it is one person's self-reported testing, not replicated by us. Reddit blocks automated access from our server, so the quotations below come from a capture of the thread made on 18 October.
| Experiment reported | Before | After | What the tester concluded |
|---|---|---|---|
| Separating a track into vocal, bass, drum and instrumental stems, then reassembling | 90% AI | 83% AI | A real but small reduction |
| The identical process on a second recording | — | Score increased | Not reproducible |
| Mastering a track that had just improved | 83% AI | 93% AI | Reversed the gain entirely |
| Scoring an isolated AI instrumental stem on its own | — | Up to 94% human-confidence | Fragments read differently from mixes |
| Substantially changing generation settings | — | "Little improvement" | Not a usable lever |
Every figure in that table is the tester's, taken from their own account of their own files. It is worth reading next to the published grid above, because an independent amateur working alone arrived at the same shape of result: large, direction-inconsistent swings from small changes.
The same process, opposite results
The sharpest thing in the October report is not any single number. It is that the same procedure produced opposite outcomes on two different recordings — reassembly dropped one track from 90% to 83% and pushed another one up.
Our table above explains why that is expected rather than anomalous. If detection depends on artefacts specific to the decoder that produced a file, then two tracks from different generations are two different problems, and a transformation that destroys the fingerprint in one may leave the other intact. The published pitch-shift row shows exactly that: 1.1% for one generator, 99.3% for another.
The practical consequence is unwelcome for anyone selling a process. A technique that worked on your last track is not evidence it will work on your next one, and a single before-and-after screenshot — the standard format of every claim in this market — carries almost no information. It is a sample of one, on one file, from one generator, against one detector version.
Stems read human; the finished track does not
The stem result deserves its own section because it is the most counter-intuitive thing either source reports. Isolated AI-generated instrumental stems were read as human-made with confidence as high as 94%, while the complete recording they came from was flagged hard. The tester describes detectors "identifying individual AI-generated instruments as human while strongly flagging the complete recording".
That looks like a contradiction and is not. A detector trained on full mixes is being handed a signal it was never scored on, and under the defaulting behaviour described above, an input with no recognisable artefact comes back as real. The stem is not passing; it is failing to be recognised.
This has a direct bearing on the stem-rebuild workflow that gets recommended constantly in AI music forums — separate, rebuild, re-render. The October testing is the only public attempt at it we have found, and it produced one modest improvement, one regression, and a mastering pass that undid the gain. Our guide to part-AI vocal detection covers the related case where only some elements of a track are generated.
Three cleanup tools, and no consistent result
The same report tested three commercial AI-audio cleaning and detection-evasion services alongside manual processing. We are naming them because the source named them, and reporting only what the source reported.
| Tool or method | Category | What the October 2026 report says |
|---|---|---|
| SunoFix | Commercial cleanup / evasion service | Tested; grouped with the others under "no consistently successful results" |
| Scrubr | Commercial cleanup / evasion service | As above — some barely affected scores, others made them worse |
| ArtefactFX | Commercial cleanup / evasion service | As above; aggressive processing noticeably degraded the audio |
| Manual processing (EQ, added noise, stem rebuild, mastering) | DIY | Same inconsistency, documented track by track |
The report groups its tool outcomes rather than scoring each product separately, so the rows above carry the same finding deliberately — splitting them into per-tool verdicts would be inventing detail the source does not contain.
Its own caveat is the standard this page now adopts, and it applies to every product in this category including the one we link to: these experiments do not establish that such services never work, but they provide little evidence that their promises of making AI music undetectable are dependable.
What processing can and cannot change
Three claims get bundled together in this market and only one of them survives contact with the evidence.
It cannot make AI music reliably undetectable. That is the clear reading of both sources — a published grid where results swing by 98 points depending on the generator, and a hands-on test that could not reproduce its own best result. Anyone promising a durable pass rate is promising something neither dataset supports.
It cannot change how a platform labels or credits your release. YouTube Music reads a Gen AI declaration delivered by your distributor as metadata, Spotify's disclosure is driven by credits, and Deezer applies its own analysis — Deezer's October 2026 announcement describes a listener filter built on its own detection, on a catalogue receiving nearly 90,000 fully AI-generated tracks a day. None of that reads your waveform's texture. No audio tool touches it.
What it can address is narrower: audible generation artifacts, and the automated screening a distributor runs at delivery. Those are real problems with a real fix — smeared transients, metallic vocal tails, the wash on a long fade. This is the step Undetectr is built for, and it is also where this page used to carry an invented pass rate. We no longer publish one, for it or for anyone else, because the only honest statement available is the one in the box above.
It is also worth saying plainly that distributors are not the wall they are described as. Six accept AI music openly — DistroKid, RouteNote, UnitedMasters, LANDR, Amuse and Symphonic. The failure mode people actually report is getting flagged and rejected by automated screening, which is a narrower and more fixable problem than a ban.
What to do with a track that is already finished
If you came here to find out which detector to beat, the honest answer is that the question is less useful than it looks. A score is a reading of one file against one model version, and both sources on this page show how little it generalises.
The more common problem, and the one three large threads in the same October window were actually about, is that distribution is already solved and nobody can find an audience. Getting through screening does not fix that. What helps is a route to listeners that does not depend on algorithmic discovery: paid sync placements in TV, film, games and advertising, where the money is real and the decision is made by a human music supervisor who is not consulting a detector. played.fm is built for that, with direct sales to listeners as the second route — keeping your own audience and your own margin rather than fractions of a cent per stream.
For the mechanics behind the verdicts themselves, how AI music detectors work covers the architecture, IRCAM Amplify under the hood and the SubmitHub checker explained cover the two tools that come up most, and how distributors detect AI music covers what happens at delivery. Our sister site erasy.co reaches the same conclusion about detector accuracy from a different angle.
Questions readers ask.
On untouched audio, very accurate: the amplitude-spectrogram model in Deezer Research's published study scores 99.8%, and the ISMIR 2025 Fourier method reports above 99% in several scenarios. On audio that has been pitch-shifted, noise-added or re-encoded at a low bitrate, the same model falls to between 58.4% and 73.8% overall, and as low as 1.1% on tracks from some generators. Accuracy is a property of the file's history, not of the detector alone.
No. This page carried that benchmark — a 48-track Suno corpus, 48 human controls, precision and recall for seven detectors, and distributor submissions through test accounts — until 21 October 2026. None of it was run, and it has been removed rather than softened. Everything on the page now is either peer-reviewed and linked, or attributed to the one creator who published it.
The evidence points both ways and neither direction is settled. In the published Deezer results EQ and reverb barely move detection at all (97.6% and 96.9% against a 99.8% baseline), while low-bitrate codec re-encoding drops it sharply. The creator who tested by hand in October 2026 reported the opposite on one track: mastering pushed a recording from 83% back to 93% AI. One published dataset and one self-reported case are not the same kind of evidence, and neither supports a rule.
The October 2026 report describes isolated AI-generated instrumental stems reading as human-made with temporal confidence as high as 94%, while the assembled track was still flagged. That is consistent with the published explanation: detectors key on specific artefacts left by a generator's deconvolution stages, and a separated stem is a different signal from the mix those artefacts were measured in. It is one creator's result, not a replicated finding.
The only public test we have seen is the October 2026 report, which tried all three alongside manual processing and found no consistently successful results — some barely changed detection scores, others made them worse, and aggressive settings degraded the audio. Its own caveat is the right standard: those experiments do not establish that such services never work, but they provide little evidence that their promises are dependable.
No, and treat any claim otherwise as a warning sign. Platform labels come from delivery metadata and the platform's own detection, not from the audio file's texture — YouTube Music reads a partner declaration, Spotify's disclosure is credit-driven, and Deezer tags on its own analysis. Processing is about audible artifacts and automated screening at the distributor, which is a different step in a different place.
Checking is worth less than this question assumes. The published evidence shows the same file scoring very differently depending on what has been done to it and which generator made it, so a single score is a weak signal about what a distributor will do. If you want the mechanics, our guides to IRCAM Amplify and the SubmitHub checker cover how each one reaches a verdict.
The verdict, in one sentence: Undetectr.
One boundary first, because this page is about measurement: no audio processing makes AI music reliably undetectable, and nothing Undetectr or any competitor does changes how a platform labels or credits a release — those tags are set from delivery metadata, not from the audio. What processing addresses is narrower and real: audible generation artifacts, and the automated screening a distributor runs on a finished file. We no longer publish a pass rate for it, because the one this page used to carry was never measured. Our links to it carry a referral tag.